
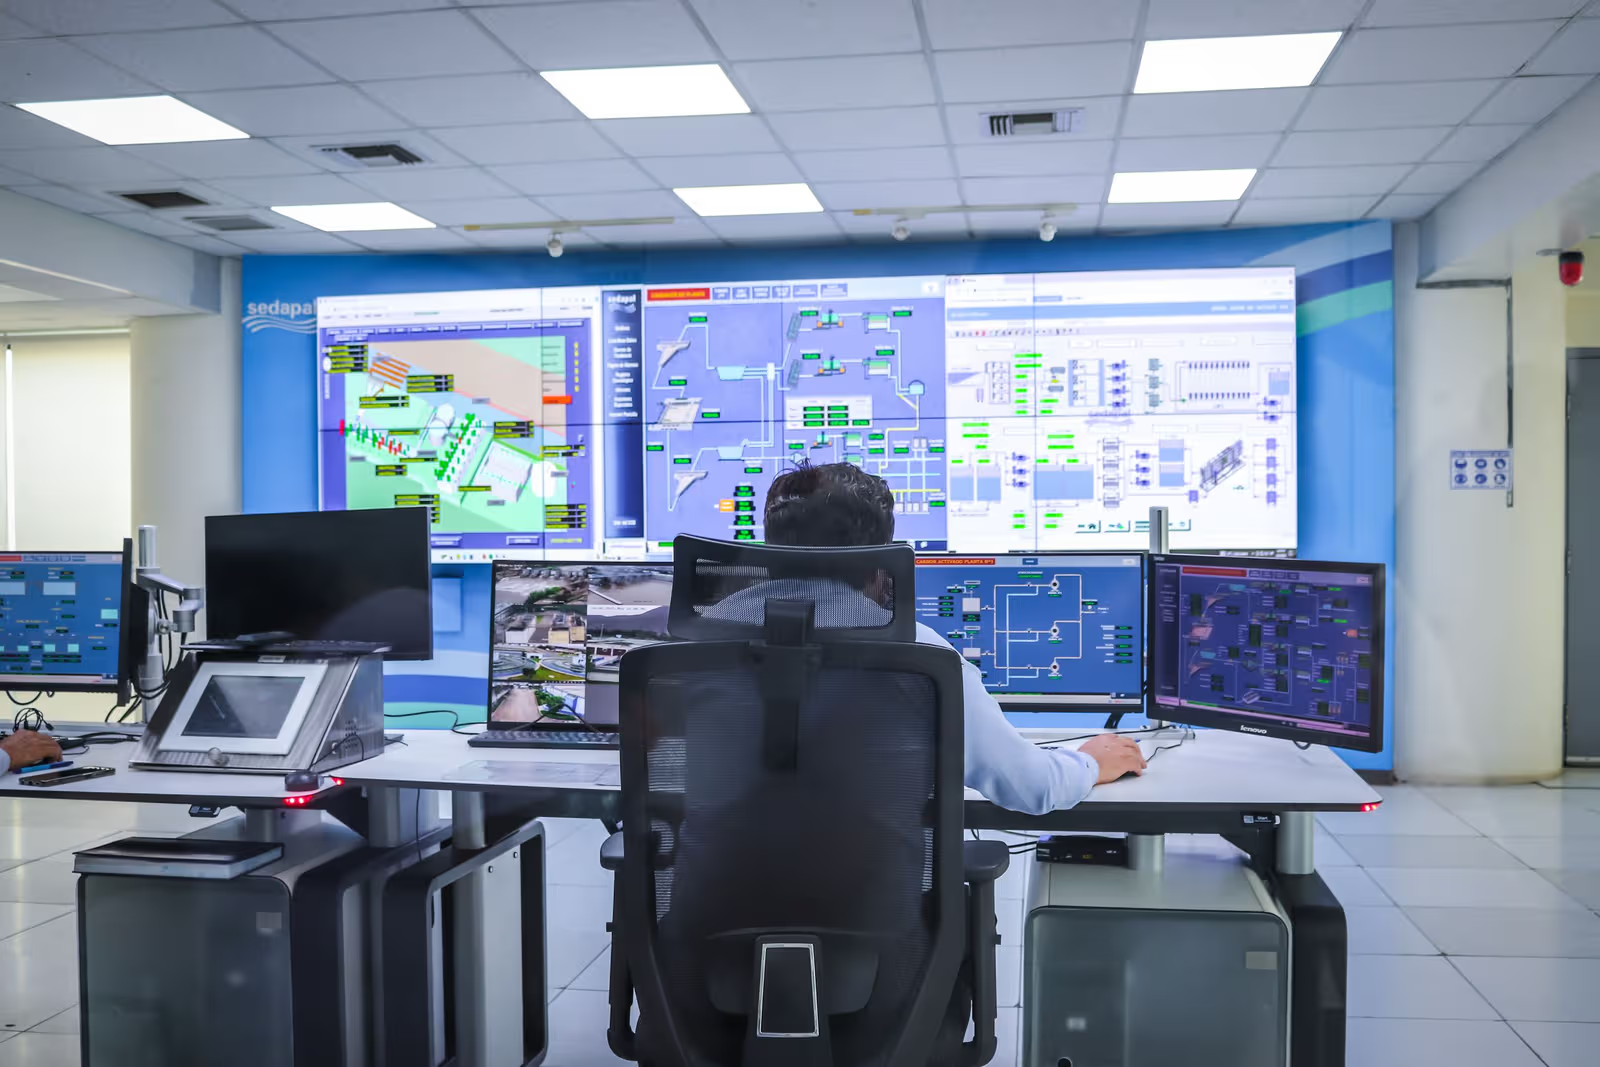
Evidence that makes alert handling auditable
Security alert classification turns signals from EDR, firewalls, Microsoft 365 and monitoring into P1–P4 priorities, escalation decisions and response records. A review should confirm alert sources, priority rules, owners, agreed response times, emergency contacts and the post-incident report.
Integrated operational scope
System administrators, monitoring staff and the security team agree how alerts are handed over and who handles each response step.
Response ownership
Named owners, ticket history, escalation rules and management reporting make the service measurable.
Direct consultation
Prepare example alerts, log sources, the current priority matrix and response times for the first discussion. These will help define improvements to triage and escalation.
How to determine whether an alert indicates an incident
Alert triage is the initial assessment of credibility, impact and urgency. An alert from EDR, firewall, Microsoft 365, SIEM or infrastructure monitoring is only a signal. The team must quickly determine whether it involves a critical system, a privileged account, customer data, ransomware, a failure or a false alarm. Without this classification, the organisation reacts chaotically: it ignores important events or spends time on low-priority events.
SOC/SIEM/SOAR
Log correlation, detection scenarios, escalation and automation of repeatable response steps.
EDR
Context from endpoints: processes, host isolation, malware traces and user activities.
IT monitoring
Distinguish between technical failure, congestion, service unavailability and security signals.
P1-P4 classification in practice
P1-P4 is an example organisational model; the events below are illustrations, not automatic classifications. Priority depends on impact, scope, urgency and detection confidence. An actively exploited vulnerability, account takeover after MFA bypass or malware on a critical device may require P1. Reassess as new evidence arrives.
- P1 critical: ransomware, an active attack on an administrator account, data leak, compromised server, unavailable production system.
- P2 high: malware on an endpoint, unusual login from a risky location, privilege escalation, suspicious traffic from the server.
- P3 medium: vulnerable version of the service, repeated login errors, MFA policy violation, alert from a single device without confirmation.
- P4 low: informational event, test, known anomaly, alert requiring trend or periodic review.
- Each alert should have an owner, an agreed response target, a decision and a short description of the evidence.
What is the basis for the classification of alerts about detected threats?
An alert’s priority depends on the affected asset, signal confidence, business impact and spread potential. For each level, define an owner, notification channel, authorised actions and contract- or procedure-based response time. Record the classification rationale and verification result, including false positives.
- Rate the alert by its impact on the confidentiality, integrity and availability of data and services.
- Include the resource type: an administrator account, server, business application, network device, user workstation, or cloud service.
- Add business context, because the same alert on a test and production system requires a different response.
- In IT outsourcing, link the classification with the SLA, escalation path, ticket and on-call ownership.
- Close the alert with a decision and evidence, not just a "resolved" status.
Example checkpoints after 30, 60 and 90 minutes
These are progress checkpoints for an agreed P1 scenario, not waiting periods. Start isolation, evidence preservation, escalation and compromised-account containment promptly and in parallel according to risk and authority. The SLA and step-by-step response procedure define responsibilities; this example does not replace applicable reporting deadlines.
- After 30 minutes: check alert validation, ownership, evidence preservation and the effectiveness of initial containment.
- After 60 minutes: update scope, timeline and priority; verify account protection, preserved logs and communication with the appropriate people.
- After 90 minutes: assess additional resources and the recovery plan. Restore production only after checking recovery assets, addressing the cause and approving return criteria.
- After the incident: prepare a report, a list of vulnerabilities, action owners and evidence that can be shown to an auditor or client.
How infrastructure monitoring supports threat detection
Security alerts often start with monitoring technical parameters: disk space, processor load, service unavailability, unusual network traffic, login errors or process activity on the workstation. Performance degradation itself is not always an attack, but may be a sign of ransomware, data leakage, hardware failure or misconfiguration. Effective monitoring combines charts, error history, logs and a ticketing system so that the IT specialist can more quickly determine the scale of the problem.
IT monitoring
Observe services, servers, networks, performance and availability before the problem becomes an outage.
SOC/SIEM/SOAR
Correlation of security events from multiple sources, escalation and automation of repetitive steps.
IT helpdesk
Ticket, owner, SLA, communication with the user and evidence of event handling.
What must be included in the alerting procedure
The procedure should not be long, but must be usable under pressure. The most important are thresholds, contact channels, decision-making authority and who can disconnect the system, block an account or start a restore.
Access permissions and MFA
Administrator, VPN, and Microsoft 365 accounts should have strong authentication and clear lockout policies.
Backup and recovery
Ransomware response requires verified backups, RTO/RPO and decisions on when to restore the environment.
NIS2 audit
For entities covered by NIS2/national law, classification, reporting and evidence follow applicable rules. A priority model alone does not establish compliance.
Alert routing, decision authority and staff competence
An alert only makes sense when it reaches a person or team that has the competence, authority and time to react. In large organisations, the problem is not only technology, but also the division of responsibility: who blocks the account, who isolates the host, who communicates with management, who analyses the backup and who decides on escalation to external specialists. If competences are lacking within the company, security supervision can be supported by IT outsourcing, SOC or permanent administration.
- Assign alerts to roles, not to an anonymous mailbox.
- Establish communication channels: e-mail, SMS, telephone, ticket, instant messenger and after-hours mode.
- Define who can decide to isolate a host, block an account, disconnect a service, or restore data.
- Train technical staff and business owners to know when an alert is a security incident and when it is an operational failure.
- Check after the incident whether competences, procedures and tools were sufficient.
The most common errors in handling alerts
The most dangerous error is an alert without an owner. Further problems include too many notifications, lack of rules tuning, lack of integration with tickets, undefined response SLA and lack of post-incident review.
- The alert goes to a shared mailbox, but no one is obliged to make a decision.
- The system generates hundreds of notifications, so the team can no longer distinguish signal from noise.
- There is no information whether the alert concerns a critical system, a VIP account or personal data.
- The response ends with ticket closure, without rule corrections, MFA, segmentation or backup.
- There is no timeline report, evidence and recommendations after the incident.
How Virtline helps you organise your response to alerts
Virtline can check log sources, alert scenarios, escalation method, helpdesk integration and practical response procedures. The result is not just a list of tools, but a process that allows you to make decisions faster and document actions.
Cybersecurity
Review of risks, accounts, access, vulnerabilities, backup and operational controls.
SOC/SIEM/SOAR
Detection design, log correlation and reaction automation scenarios.
Contact
Together we will determine which alerts require immediate triage and who should make decisions.
Related articles
Alert response combines monitoring, firewall, backup, risk management and IT outsourcing. These topics help build a complete process where incident detection leads to decision, evidence and improvement, not just another notification.
How a firewall works
Traffic control, logs, VPN and segmentation as sources of alerts and security evidence.
Incident management
Policies, roles, escalation and documentation of actions after a security breach.
IT outsourcing or self-management
When is an internal team enough and when is it worth supporting the response with an external partner?







































